Case study / Product / 2025
Google Search | Testing AI-driven “What People Are Saying” with real users
Google had trained a new AI feature on synthetic models and wanted to understand whether it was resonant and relevant for real people. A hybrid research study using Fabric and deep 1:1 interviews answered that before rollout, and, unexpectedly, gave their model something to learn from too.
The context
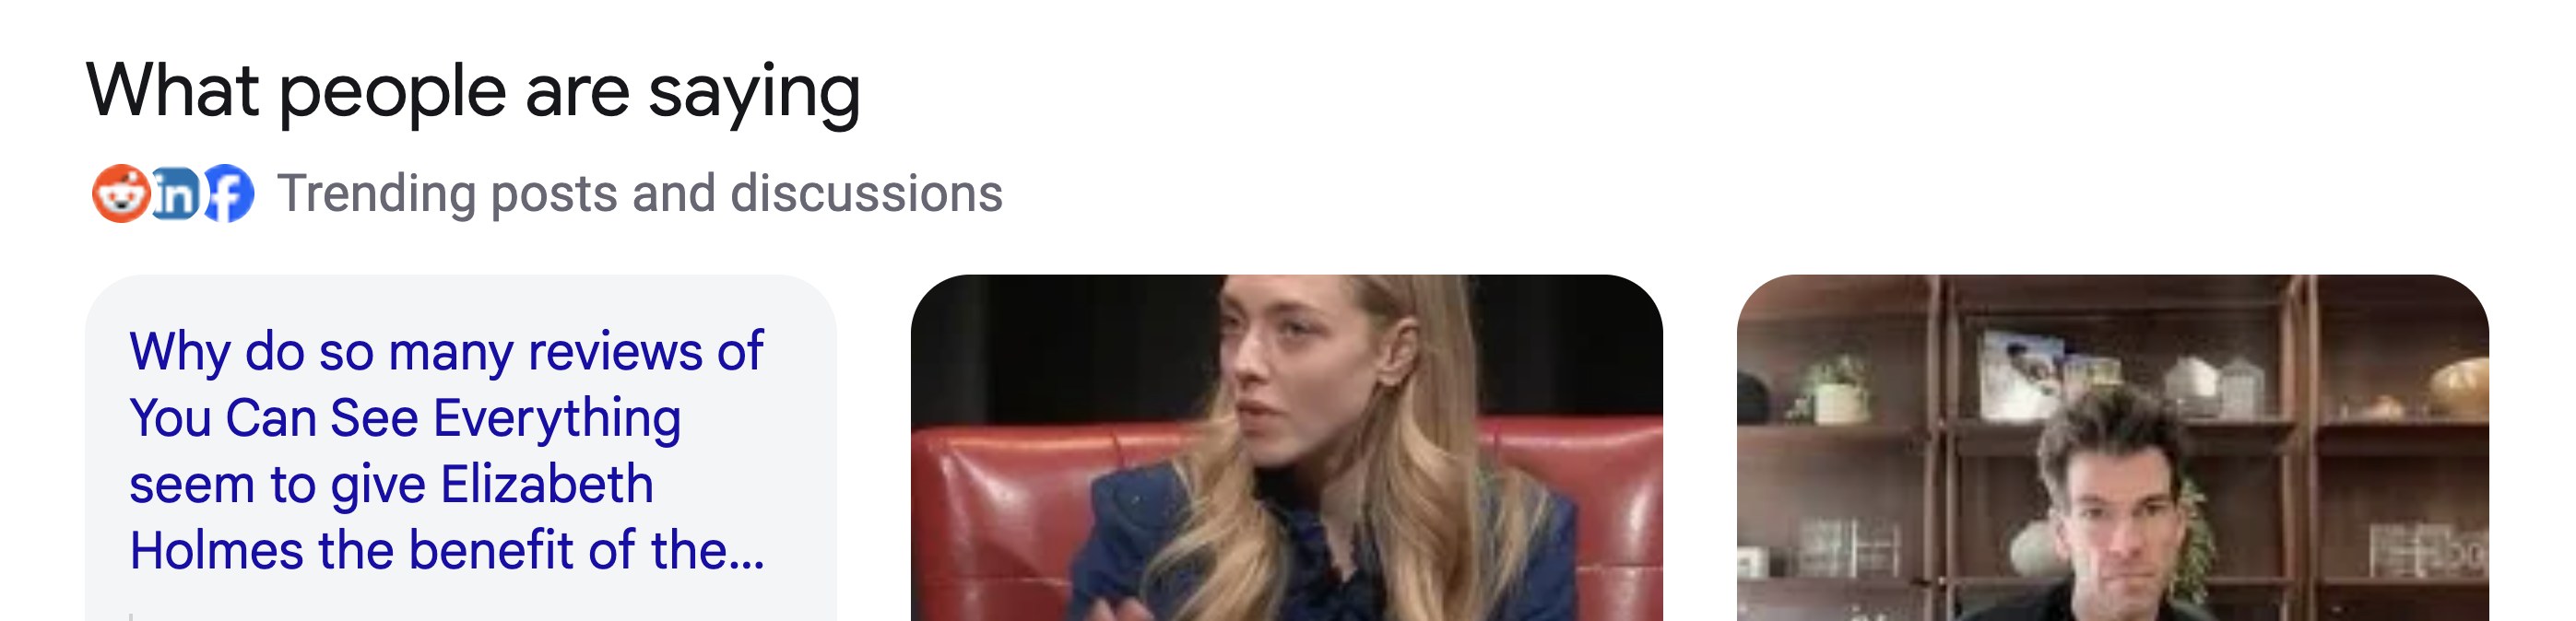
Google Search engineered a new AI feature, “What People Are Saying,” designed to pull real-time social media perspectives directly into News search results. It was a meaningful shift: search results that don’t just point to a story but surface what people are actually saying about it, as it happens.
The system had been developed and trained using internal synthetic models. That got the feature working. The next question was how it would land with real people: whether they would trust it, use it, or scroll past it.
The open question
The brief came down to one thing: validate the feature with real people before launch. Did it resonate, was it relevant, and where did reality differ from what the models anticipated? That meant looking past “do they like it” to the harder questions. What makes a social perspective inside a search result feel credible? Where do expectations and reality diverge? When does dynamic content help someone understand a news story, and when does it get in the way?
Synthetic models can tell you a feature works. Only real people can tell you whether they believe it.
Designing the study
I architected a hybrid study with two layers. The asynchronous layer ran on Fabric: [ask: how many] participants responded on video to [ask: how many] prompts as they encountered the feature, giving us authentic, unrehearsed reactions at scale, with transcripts to match. The synchronous layer was a set of deep 1:1 interviews, where we could slow down, probe the moments that stood out in the async footage, and watch people work through a result in real time.
The two layers did different jobs. Async gave breadth and honesty; people say things to a camera on their own time that they soften in a room. The 1:1s gave depth, and the chance to ask “why” when a reaction didn’t match what the models predicted.
What we evaluated
Three things, consistently, across every session: authentic user sentiment toward the feature, the trust markers people relied on when deciding whether a social perspective was worth taking seriously, and the expectation gaps between what they assumed the feature would do and what it actually did.
The outcome nobody planned for
The feedback went straight into refining Google’s underlying models prior to rollout. That was the expected outcome. The unexpected one was that Google used Fabric’s raw data itself to help train the model. The research didn’t just evaluate the AI; it became part of what the AI learned from.
Launch, and what it set up
The feature launched successfully and has driven consistent month-over-month growth since. Just as important for how Google works going forward, the study established a model for testing dynamic AI search features with real users before they ship: hybrid async and sync research, run against the questions synthetic data can’t answer.
A Product x AI case study.